What €150–€25,000 Buys: Workflow Automation Costs for Lithuanian SMEs
September 14, 2026
If your data is sensitive, a private LLM for business use is worth pursuing, and the pragmatic starting point is retrieval augmented generation (RAG), not fine-tuning. RAG keeps your documents inside your own systems, produces traceable answers, and costs far less to update than retraining a model. Fine-tuning earns its place later, once you know exactly which behaviour needs to be permanent.
TL;DR:
- Retrieval augmented generation offers a cost-effective, traceable way to deploy private LLMs, allowing updates through index modifications rather than retraining models.
- Most SMEs should start with RAG due to its speed, lower technical barriers, and ability to provide source citations, before considering fine-tuning for strict domain consistency.
- Infrastructure requirements include an inference engine, vector database, ingestion pipeline, orchestration layer, and secure logging, with deployment costs depending on model size and hosting location.
- Governance controls such as data classification, PII redaction, encryption, audit logs, and role-based access are critical to comply with regulations and maintain trust.
- A successful private LLM project begins with a narrow scope, usually a pilot for one department or document set, before scaling and adding fine-tuning only if needed for specific, recurring outputs.
Table of Contents
- What is a private LLM and where does it actually help?
- RAG, fine-tuning or hybrid: which architecture fits?
- What infrastructure does a private LLM actually need?
- Which security and governance controls are non-negotiable?
- How do you choose a supplier or delivery model?
- From pilot to production: what is the realistic roadmap?
- How does a private LLM fit your existing IT systems?
- How do you keep a private LLM accurate and secure over time?
- Done’s perspective on private LLM projects for SMBs
- How Done can help with a private LLM pilot
- Sources
- FAQ
What is a private LLM and where does it actually help?
A private LLM runs on infrastructure your business controls, whether that is on-premise hardware, a private cloud instance, or an EU-hosted environment, rather than sending your prompts to a shared public API. The model, the documents it references, and the logs it generates all stay inside your own perimeter. That distinction matters because public LLM services process your prompts on someone else’s infrastructure, under someone else’s terms.
We have seen this pattern repeat across regulated clients: the moment client files, medical notes, or financial records touch a prompt, the calculation changes.
The realistic use cases we encounter most often:
- Internal helpdesk assistants that answer staff questions from HR policies or IT manuals
- Document Q&A tools that let staff query contracts, reports, or technical specifications in plain language
- Contract review summaries that flag clauses needing legal attention
- Workflow automation that drafts routine correspondence or classifies incoming requests
If your data is public-facing marketing copy or general research, a public API is usually fine. If it is client records, health data, or anything covered by professional confidentiality, a private deployment stops being optional.
RAG, fine-tuning or hybrid: which architecture fits?
This is the decision most SMEs get stuck on, and the answer depends on how much you need the model’s behaviour to change versus how much you just need it to know things.
- RAG (retrieval augmented generation) retrieves relevant document passages at query time and feeds them to the model as context. Nothing is baked into the model itself, so updating an index is far cheaper than retraining, and every answer can point back to its source document.
- Fine-tuning adjusts the model’s weights so it consistently adopts a tone, format, or specialised vocabulary. It needs open-weight model access, more engineering effort, and a governance process to track what changed and why.
- Hybrid (RAG plus fine-tuning) combines both. Enterprise teams increasingly pair fine-tuning with retrieval to get consistent domain behaviour without sacrificing up-to-date facts.
For most regulated use cases, RAG wins on traceability alone. An auditor can ask “where did this answer come from?” and get a real citation, not a shrug. Fine-tuning, by contrast, changes the model itself, which makes it harder to explain a specific output months later.
Pro Tip: Start every project as RAG-only. Only add fine-tuning once you can name the exact behaviour RAG cannot deliver, such as a rigid output format or a house style the model keeps ignoring.
Enterprise practice generally prefers RAG first for speed and traceability, adding fine-tuning only where consistent behaviour is critical and the organisation can host open-weight models to fine-tune in the first place.
What infrastructure does a private LLM actually need?
Cost conversations go sideways quickly when the components aren’t named. Here is what actually sits behind a working deployment:
- Inference engine: the software that runs the model and serves responses (examples include vLLM or Ollama for open models)
- Vector database: stores document embeddings for retrieval (Qdrant, Weaviate, or pgvector are common choices)
- Ingestion pipeline: converts PDFs, emails, and internal wikis into searchable chunks
- Orchestration layer: routes queries, manages prompts, and chains retrieval with generation
- Logging and monitoring: records every query and answer for audit purposes
Sizing depends entirely on model size. A 7 to 13 billion parameter open model runs comfortably on a single 24GB GPU. Anything larger, or any workload with concurrent users, usually needs multiple GPUs. Storage and IOPS matter more than people expect once document volumes climb into the tens of thousands of pages.
On deployment location: on-premise gives maximum control but the highest upfront cost; private cloud reduces hardware ownership; an EU-hosted cloud environment is often the practical middle ground for procurement, keeping data within EU borders while avoiding a server room. SMB-focused RAG deployments on platforms like Azure tend to scale faster than on-premise builds precisely because the managed services absorb much of this complexity.
Which security and governance controls are non-negotiable?
Skipping governance is the single most common mistake we see in early-stage AI projects, and it is the one that gets noticed by a regulator or a client audit, not by a developer.
Required controls, in our experience, include:
- Data classification before anything reaches a model, so sensitive fields are flagged and routed correctly
- PII detection and redaction applied before prompts leave the ingestion pipeline
- Customer-managed encryption keys (BYOK) and private network endpoints, keeping inference traffic off the public internet
- Full audit logs with source traceability for every generated answer
- Role-based access control (RBAC) and defined retention periods for logs and documents
Self-hosted deployments that keep prompts, documents, and model weights inside an organisation’s own perimeter are specifically designed to avoid data being used to train an external provider’s model, which is the core sovereignty question GDPR and the EU AI Act both push towards.
Implementing PII detection and redaction as a standard layer before any prompt reaches a model, rather than as an afterthought, tends to separate projects that pass an internal audit from those that need rebuilding six months in.
How do you choose a supplier or delivery model?
A proposal that looks technically impressive can still fail on governance basics. Run every supplier conversation through this checklist:
- Data residency: where exactly does the data sit, physically and legally, and can they name the jurisdiction in writing?
- GDPR practice: do they have a documented data processing agreement, not just a verbal assurance?
- Model control: do you own the fine-tuned weights, or are you locked into their hosting indefinitely?
- SLA clarity: what uptime and response times are guaranteed, and what happens if they are missed?
- Pricing transparency: is the quote itemised by infrastructure, engineering, and maintenance, or is it a single vague number?
Ask directly: “Can you show me an audit log from a comparable deployment?” and “What happens to our data if we terminate the contract?” A vendor-neutral view on private versus public models notes that private deployments demand higher upfront investment but hand you real control over intellectual property and compliance, which is exactly what a serious proposal should reflect in its pricing.
Red flags: vague answers on data location, no mention of encryption key ownership, and pricing that only covers the pilot with no shape for production costs.
From pilot to production: what is the realistic roadmap?
A pilot typically runs four to eight weeks and should cover one narrow use case, such as document Q&A over a single department’s files, not the whole organisation at once.
Production rollout concentrates engineering effort on three things:
- Scaling the ingestion pipeline to handle the full document set, not the pilot sample
- Hardening security controls (RBAC, key management, network isolation) for real usage volumes
- Building monitoring dashboards that track accuracy, source traceability, and cost per query
Cost shape typically front-loads infrastructure and integration work, then settles into a lower ongoing spend for maintenance and monitoring. A pragmatic pilot measures accuracy, source traceability, and user adoption rather than chasing fine-tuning improvements before the basic retrieval loop is proven. Track user adoption honestly. A technically flawless tool nobody opens has failed regardless of the accuracy score.
How does a private LLM fit your existing IT systems?
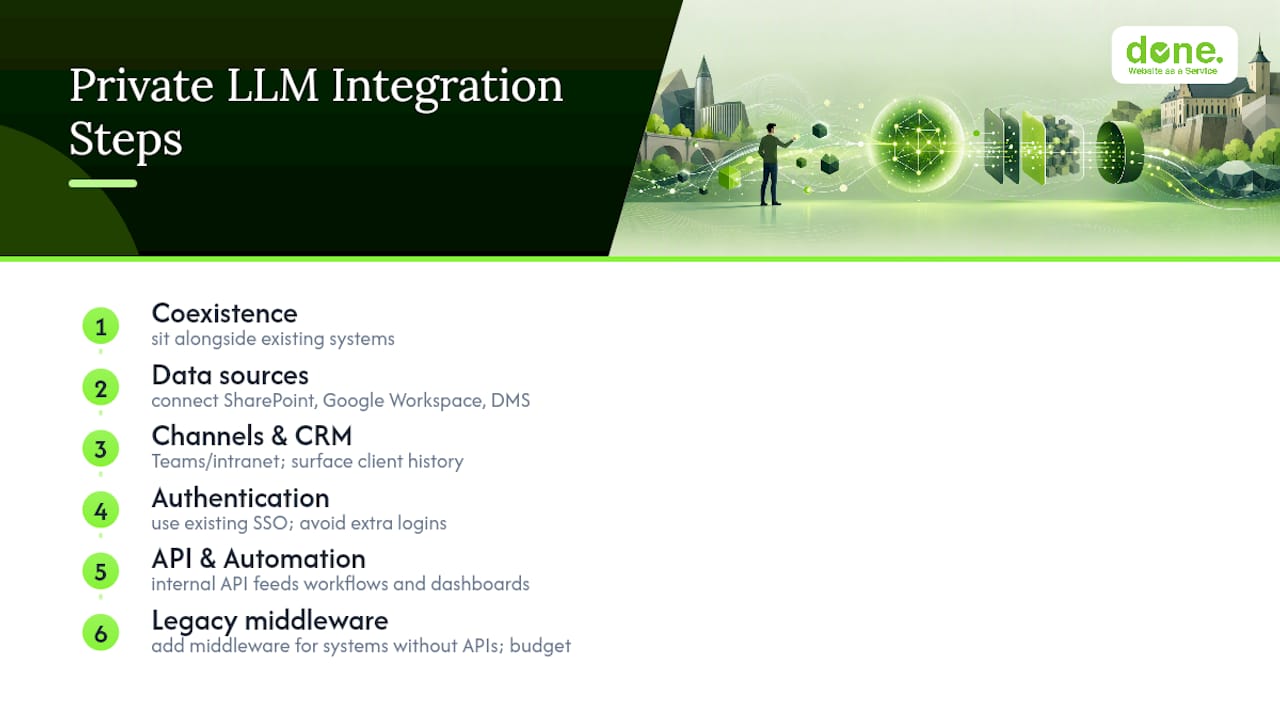
Integration is where most projects either click into place or stall for months. The private LLM rarely needs to replace anything. It needs to sit alongside what you already have.
Practically, this means connecting the model to your existing document stores (SharePoint, Google Workspace, or a document management system), your CRM, and whichever communication channel staff already use, such as Microsoft Teams or an internal intranet. A well-scoped CRM integration with AI can turn a private LLM from a standalone chatbot into something that actually surfaces client history alongside its answers.
Authentication is the part people underestimate. If staff already log in via single sign-on, the LLM interface should sit behind the same authentication layer, not a separate login nobody remembers. Every additional login is a reason not to use the tool.
API design also matters more than the model choice itself. A private LLM exposed through a clean internal API can feed into automation workflows, ticketing systems, or reporting dashboards without staff ever opening a separate chat window. That is often where the real productivity gain sits, not in the chat interface but in the quiet automation running behind it. Businesses already running marketing automation workflows tend to find this the most natural entry point, since the orchestration layer already exists.
One practical constraint worth flagging early: legacy systems with no API, common in older ERP or accounting software, often need a middleware layer before any LLM can talk to them. Budget for that conversation before the contract is signed, not after.
How do you keep a private LLM accurate and secure over time?
A private LLM is not a one-off installation. Documents change, staff turnover shifts institutional knowledge, and model providers release updates that can shift behaviour.
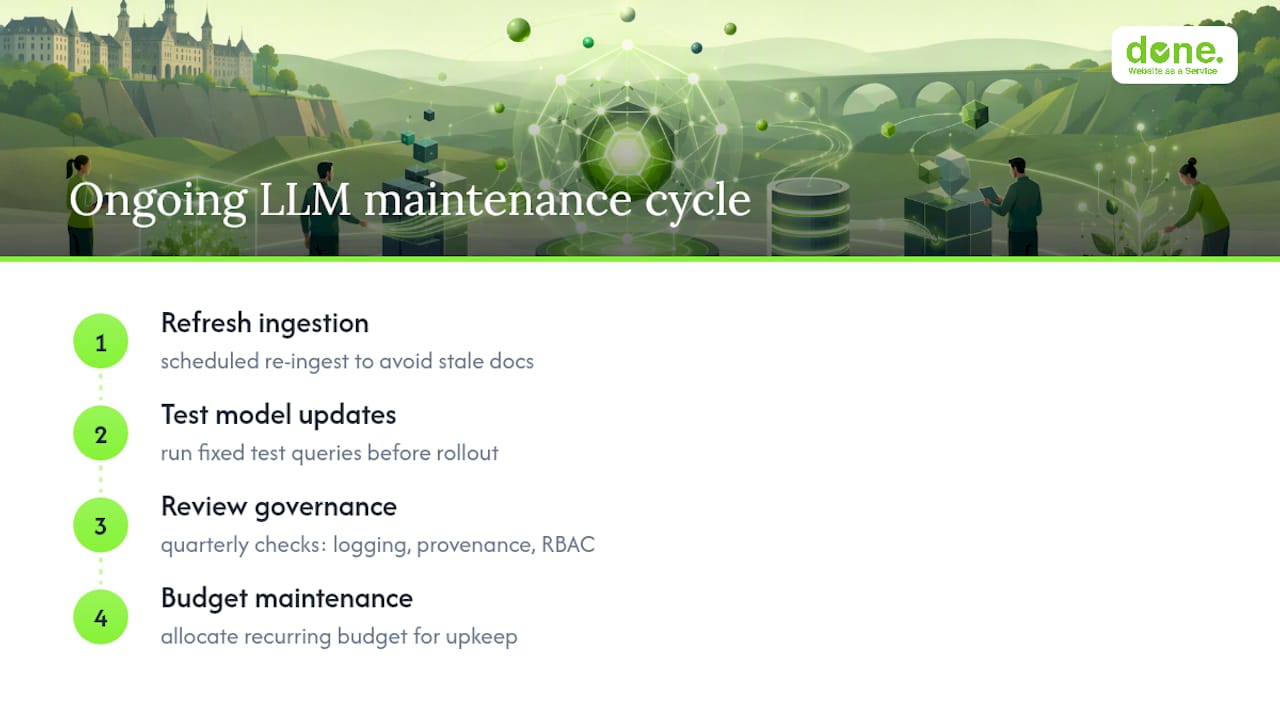
The ingestion pipeline needs a refresh schedule, not a one-time load. Contracts get renewed, policies get revised, and a document Q&A tool answering from an 18-month-old policy manual is worse than no tool at all, because staff trust it by default.
Model updates need a testing step before rollout. If you are running an open-weight model, a new version might change output formatting or introduce subtly different behaviour on edge cases. Run new versions against a fixed set of test queries before switching production traffic over.
Governance also needs revisiting on a schedule, not just at launch. Access lists drift as people change roles. Retention periods that made sense at launch may need adjusting as document volumes grow. Enterprise governance checklists consistently flag audit logging, source provenance, and role-based access as the three controls that degrade fastest without a scheduled review, typically quarterly for smaller deployments.
Budget for this ongoing layer explicitly. A common mistake is pricing the build and forgetting the maintenance, then being surprised when the tool’s accuracy quietly drifts six months later.
Done’s perspective on private LLM projects for SMBs
In our experience, the projects that succeed are the ones that start narrow. A single department, a single document set, a pilot with a defined accuracy target lasting several weeks. The ones that stall are the ones trying to solve every department’s AI ambitions in one build.
We lean towards RAG first for almost every client, because hybrid approaches demand both machine learning and data engineering skills that most SMEs simply do not have in-house yet, and a managed pilot closes that gap without locking you into unnecessary complexity. We recommend hybrid only when a client can point to a specific, recurring output problem that RAG alone cannot fix, such as a rigid compliance phrasing that keeps drifting.
Private deployment fits best where confidentiality is the job, not the afterthought: legal file review, financial document summarisation, healthcare intake support. For a marketing agency asking general research questions, a public API is often still the sensible answer.
— Thomas
How Done can help with a private LLM pilot
There are other routes to this: hiring a full-time ML engineer, or committing straight to a large systems integrator contract. Both work, but both assume you already know exactly what you want built, and most SMEs do not, not on day one.
Done is the practical alternative for a Luxembourg SME weighing up a private LLM: no long build-first commitment, a scoped audit before any infrastructure spend, and a team that has already run 350+ digital and AI projects since 2014. We start with a short audit of your data and use case, move into a pilot with a defined accuracy target, and only recommend secure deployment and staff training once the pilot proves the case. Our AI consulting work has taken clients from a vague “we should look at AI” brief to a working document Q&A tool inside weeks, not quarters.
If your business handles client files, financial records, or health data and you are weighing a private LLM for business use, book an audit or pilot scoping call with Done and get a concrete cost shape before you commit to anything.
Sources
- RAG vs Fine‑Tuning Enterprise: A Decision Guide for 2026
- RAG vs Fine Tuning: Enterprise Decisions for AI Models and AI Systems | Databricks Blog
- Private AI & Self‑Hosted LLMs, GDPR‑Compliant
- Enterprise RAG architecture for SMBs on Azure
FAQ
What is a private LLM for business?
A private LLM runs on infrastructure a business controls, on-premise or in a private/EU-hosted cloud, keeping prompts and documents inside its own perimeter rather than a shared public API.
Is RAG or fine-tuning better for a private AI project?
RAG is usually the better starting point because it is cheaper to update and gives traceable answers; fine-tuning suits cases needing permanent, consistent behaviour baked into the model itself.
How long does a private LLM pilot take?
A well-scoped pilot typically runs four to eight weeks, covering one department or document set before any production rollout begins.
Does a private LLM guarantee GDPR compliance?
No single deployment guarantees compliance, but keeping data, prompts and weights inside your own perimeter with proper access controls and PII redaction supports GDPR and EU AI Act alignment.
Can Done help deploy a private LLM in Luxembourg?
Yes, Done runs audits and scoped pilots for SMEs handling sensitive data, moving from a defined pilot into secure deployment and staff training once results are proven.